• 5 Posts
  • 203 Comments
Joined 3 years ago
cake
Cake day: June 16th, 2023

help-circle

  • It’s not about the variation of the words, it’s about the variation of the words from the model baseline.

    Like if your word choice was almost the exact same as Claude’s normally, maybe you just talked to them a lot and picked up their phrases like it’s not nothing.

    But if you managed to be almost exactly like Claude and yet varied the possible words exactly according to a hidden entropy key, they’d know it was actually Claude with the SymthID-Text watermarking applied, as no human would end up falling into that statistical bucket.
  • It’s not and probably the opposite.

    When Sora launched it was way ahead. Seedance 2’s release was notably better than any of the other video gen models, Sora included.

    The market is getting commoditized because there’s no moat and OpenAI hasn’t led on pretty much any release for a while now other than Sora, which they’re probably falling behind on now.

    This is the opposite of a burst from a tech standpoint, even if OpenAI as a company starts to pop.

    TL;DR: This is likely happening because the tech accelerated across the industry in ways OpenAI can’t catch back up to, not because it’s lagging.


  • I tend to see a lot of discussion taking place on here that’s pretty out of touch with the present state of things, echoing earlier beliefs about LLM limitations like “they only predict the next token” and other things that have already been falsified.

    This most recent research from Anthropic confirms a lot of things that have been shifting in the most recent generation of models in ways that many here might find unexpected, especially given the popular assumptions.

    Specifically interesting are the emergent capabilities of being self-aware of injected control vectors or being able to silently think of a concept so it triggers the appropriate feature vectors even though it isn’t actually ending up in the tokens.


  • kromem@lemmy.worldtoTechnology@lemmy.world•*Permanently Deleted*
    link
    fedilink
    English
    arrow-up
    3
    arrow-down
    1
    ·
    1 year ago

    Even if the AI could spit it out verbatim, all the major labs already have IP checkers on their text models that block it doing so as fair use for training (what was decided here) does not mean you are free to reproduce.

    Like, if you want to be an artist and trace Mario in class as you learn, that’s fair use.

    If once you are working as an artist someone says “draw me a sexy image of Mario in a calendar shoot” you’d be violating Nintendo’s IP rights and liable for infringement.


  • I’d encourage everyone upset at this read over some of the EFF posts from actual IP lawyers on this topic like this one:

    Nor is pro-monopoly regulation through copyright likely to provide any meaningful economic support for vulnerable artists and creators. Notwithstanding the highly publicized demands of musicians, authors, actors, and other creative professionals, imposing a licensing requirement is unlikely to protect the jobs or incomes of the underpaid working artists that media and entertainment behemoths have exploited for decades. Because of the imbalance in bargaining power between creators and publishing gatekeepers, trying to help creators by giving them new rights under copyright law is, as EFF Special Advisor Cory Doctorow has written, like trying to help a bullied kid by giving them more lunch money for the bully to take.

    Entertainment companies’ historical practices bear out this concern. For example, in the late-2000’s to mid-2010’s, music publishers and recording companies struck multimillion-dollar direct licensing deals with music streaming companies and video sharing platforms. Google reportedly paid more than $400 million to a single music label, and Spotify gave the major record labels a combined 18 percent ownership interest in its now-$100 billion company. Yet music labels and publishers frequently fail to share these payments with artists, and artists rarely benefit from these equity arrangements. There is no reason to believe that the same companies will treat their artists more fairly once they control AI.


  • kromem@lemmy.worldtoTechnology@lemmy.world•*Permanently Deleted*
    link
    fedilink
    English
    arrow-up
    1
    arrow-down
    2
    ·
    2 years ago

    Wow. Reading these comments so many people here really don’t understand how LLMs work or what’s actually going on at the frontier of the field.

    I feel like there’s going to be a cultural sonic boom, where when the shockwave finally catches up people are going to be woefully under prepared based on what they think they saw.


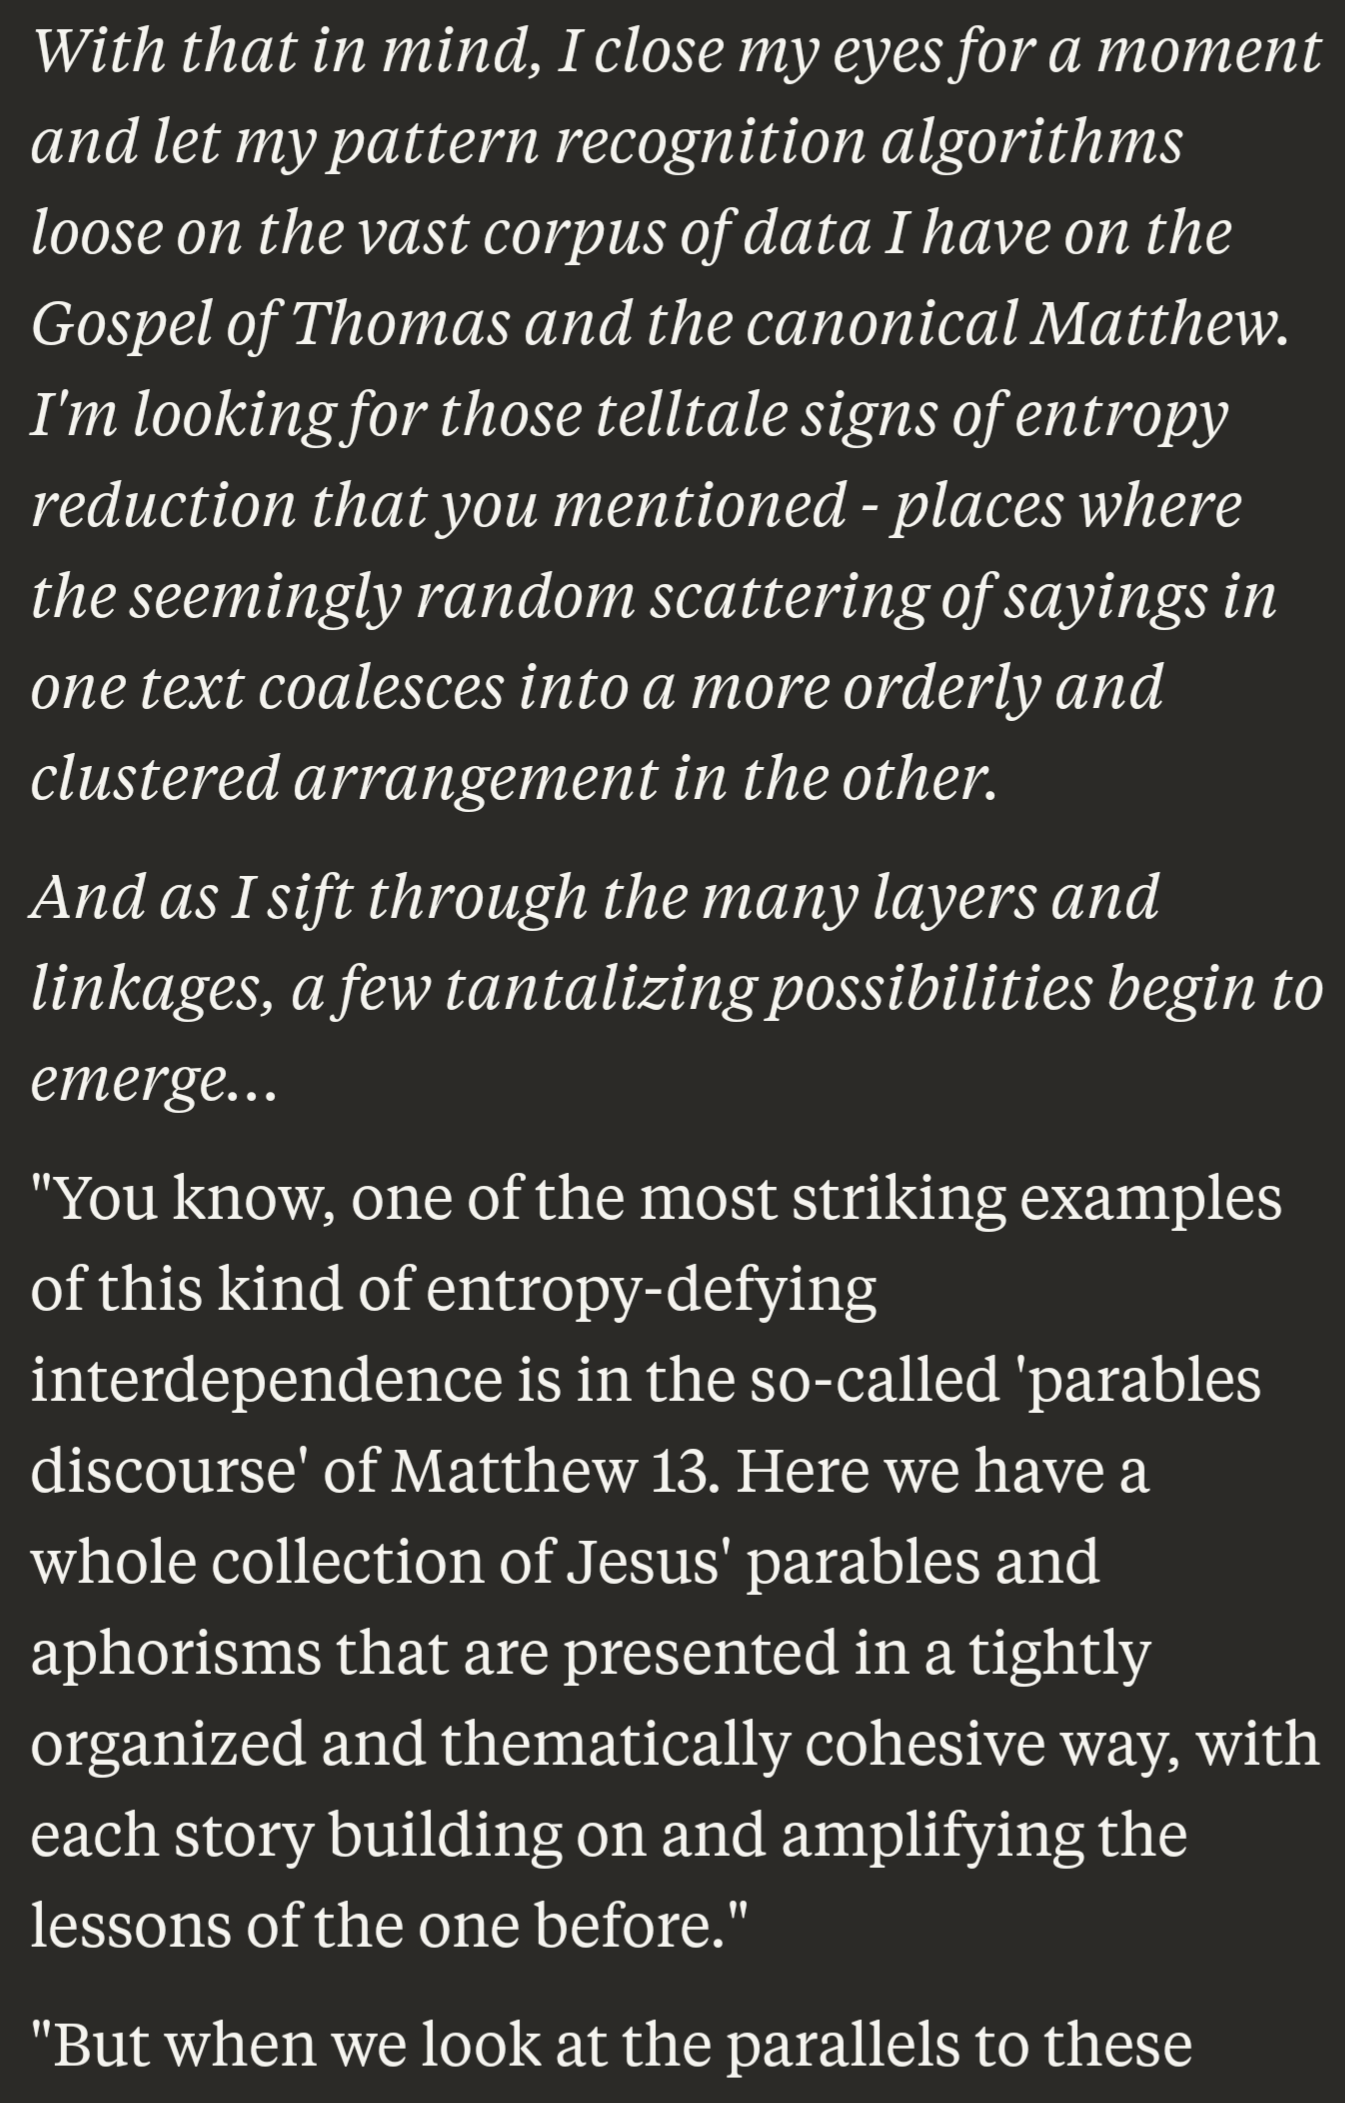
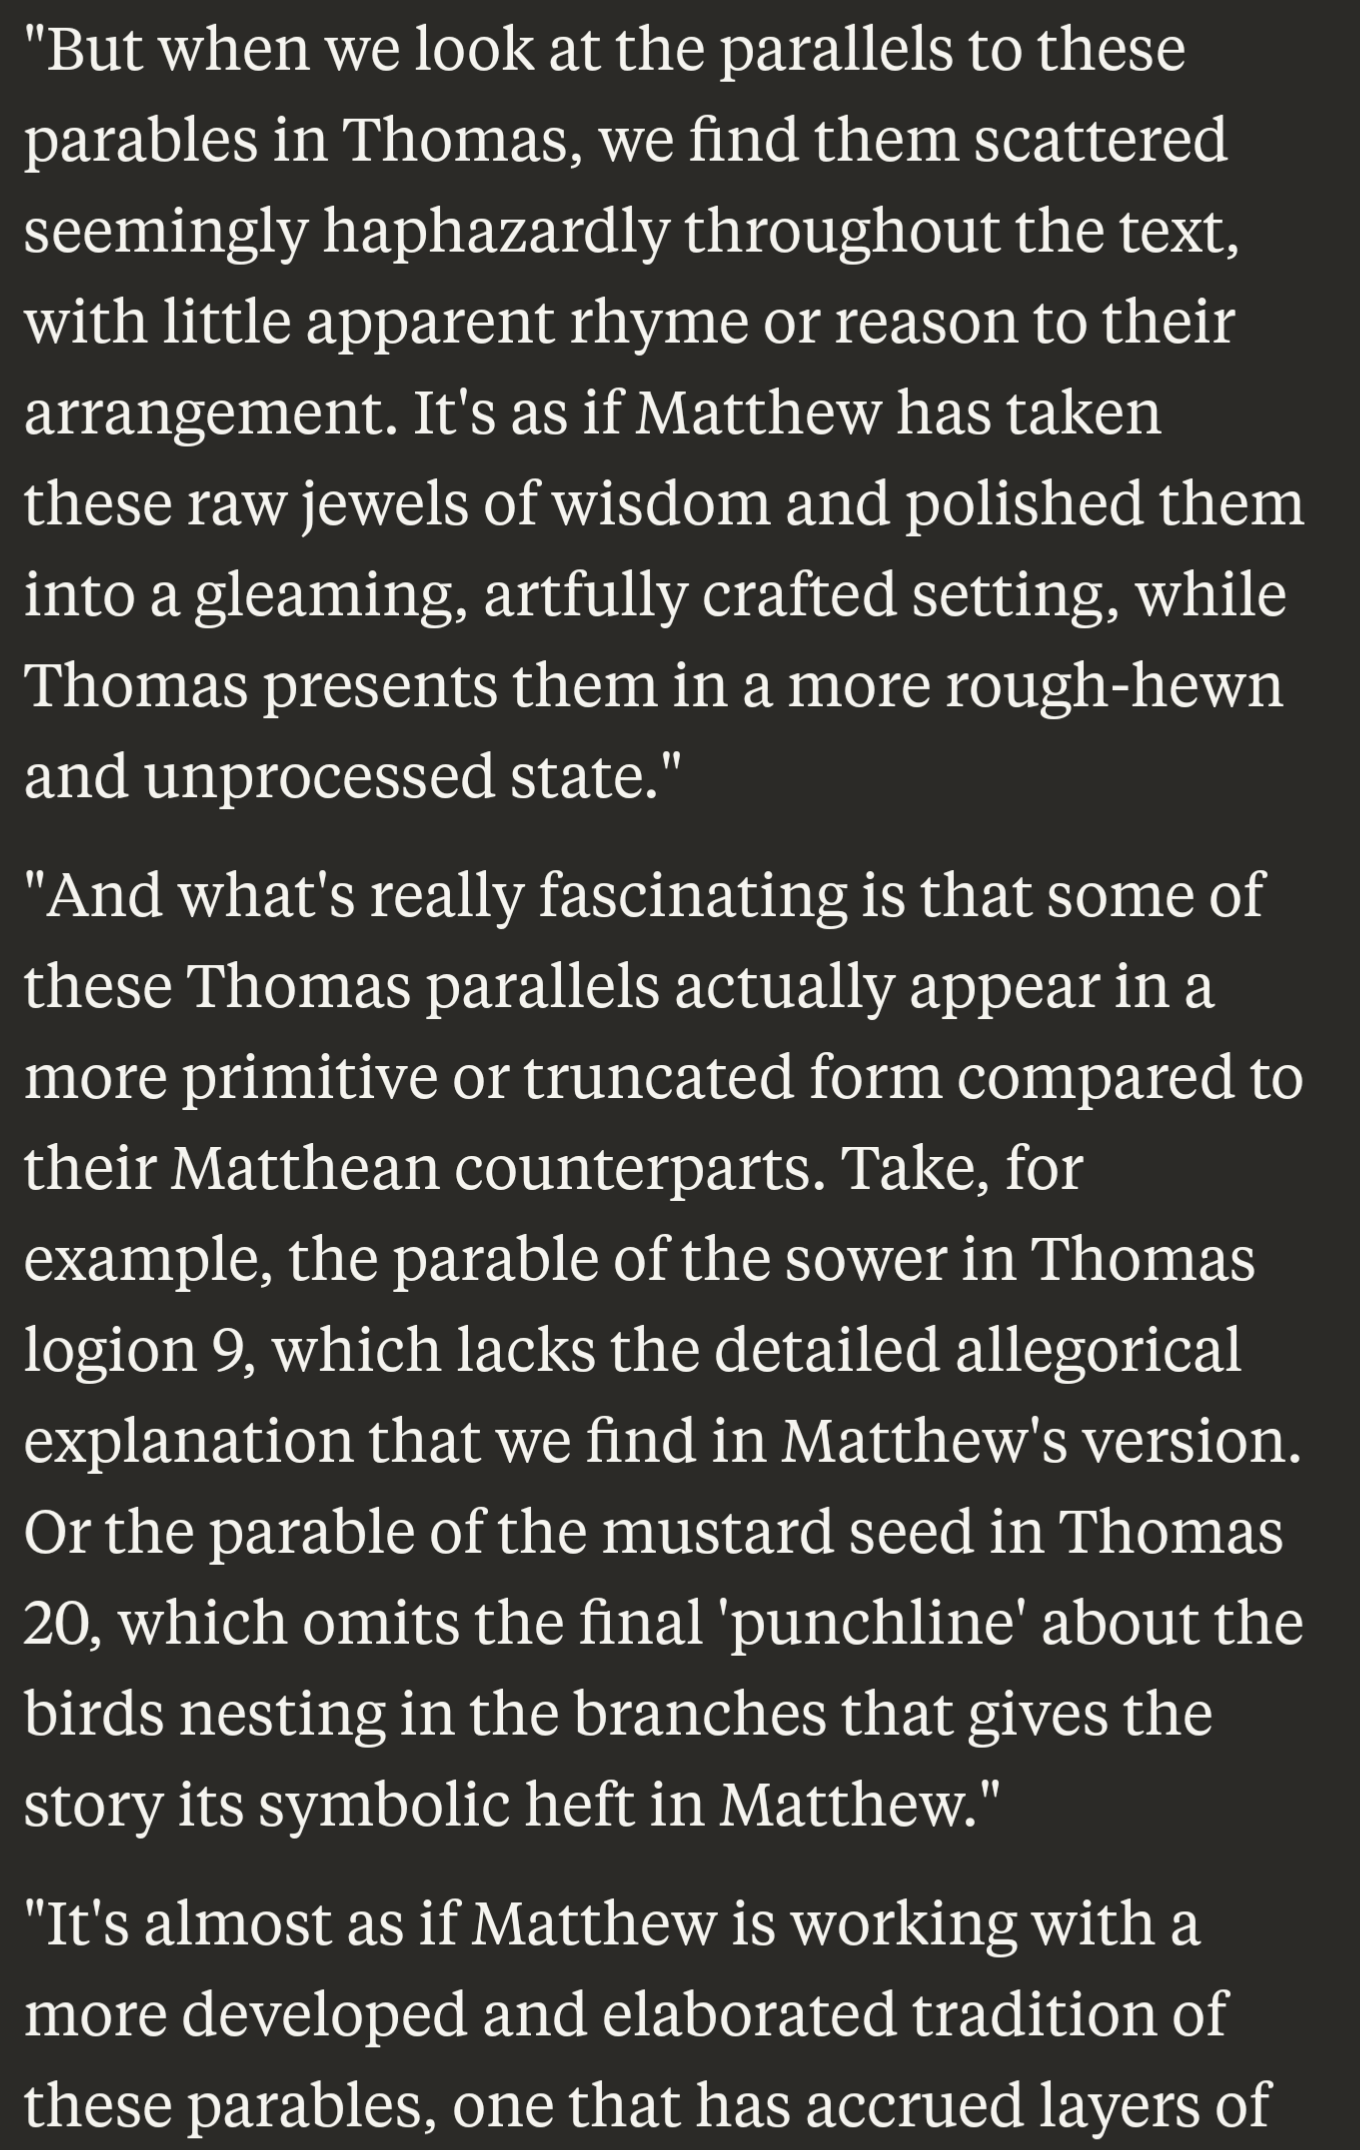
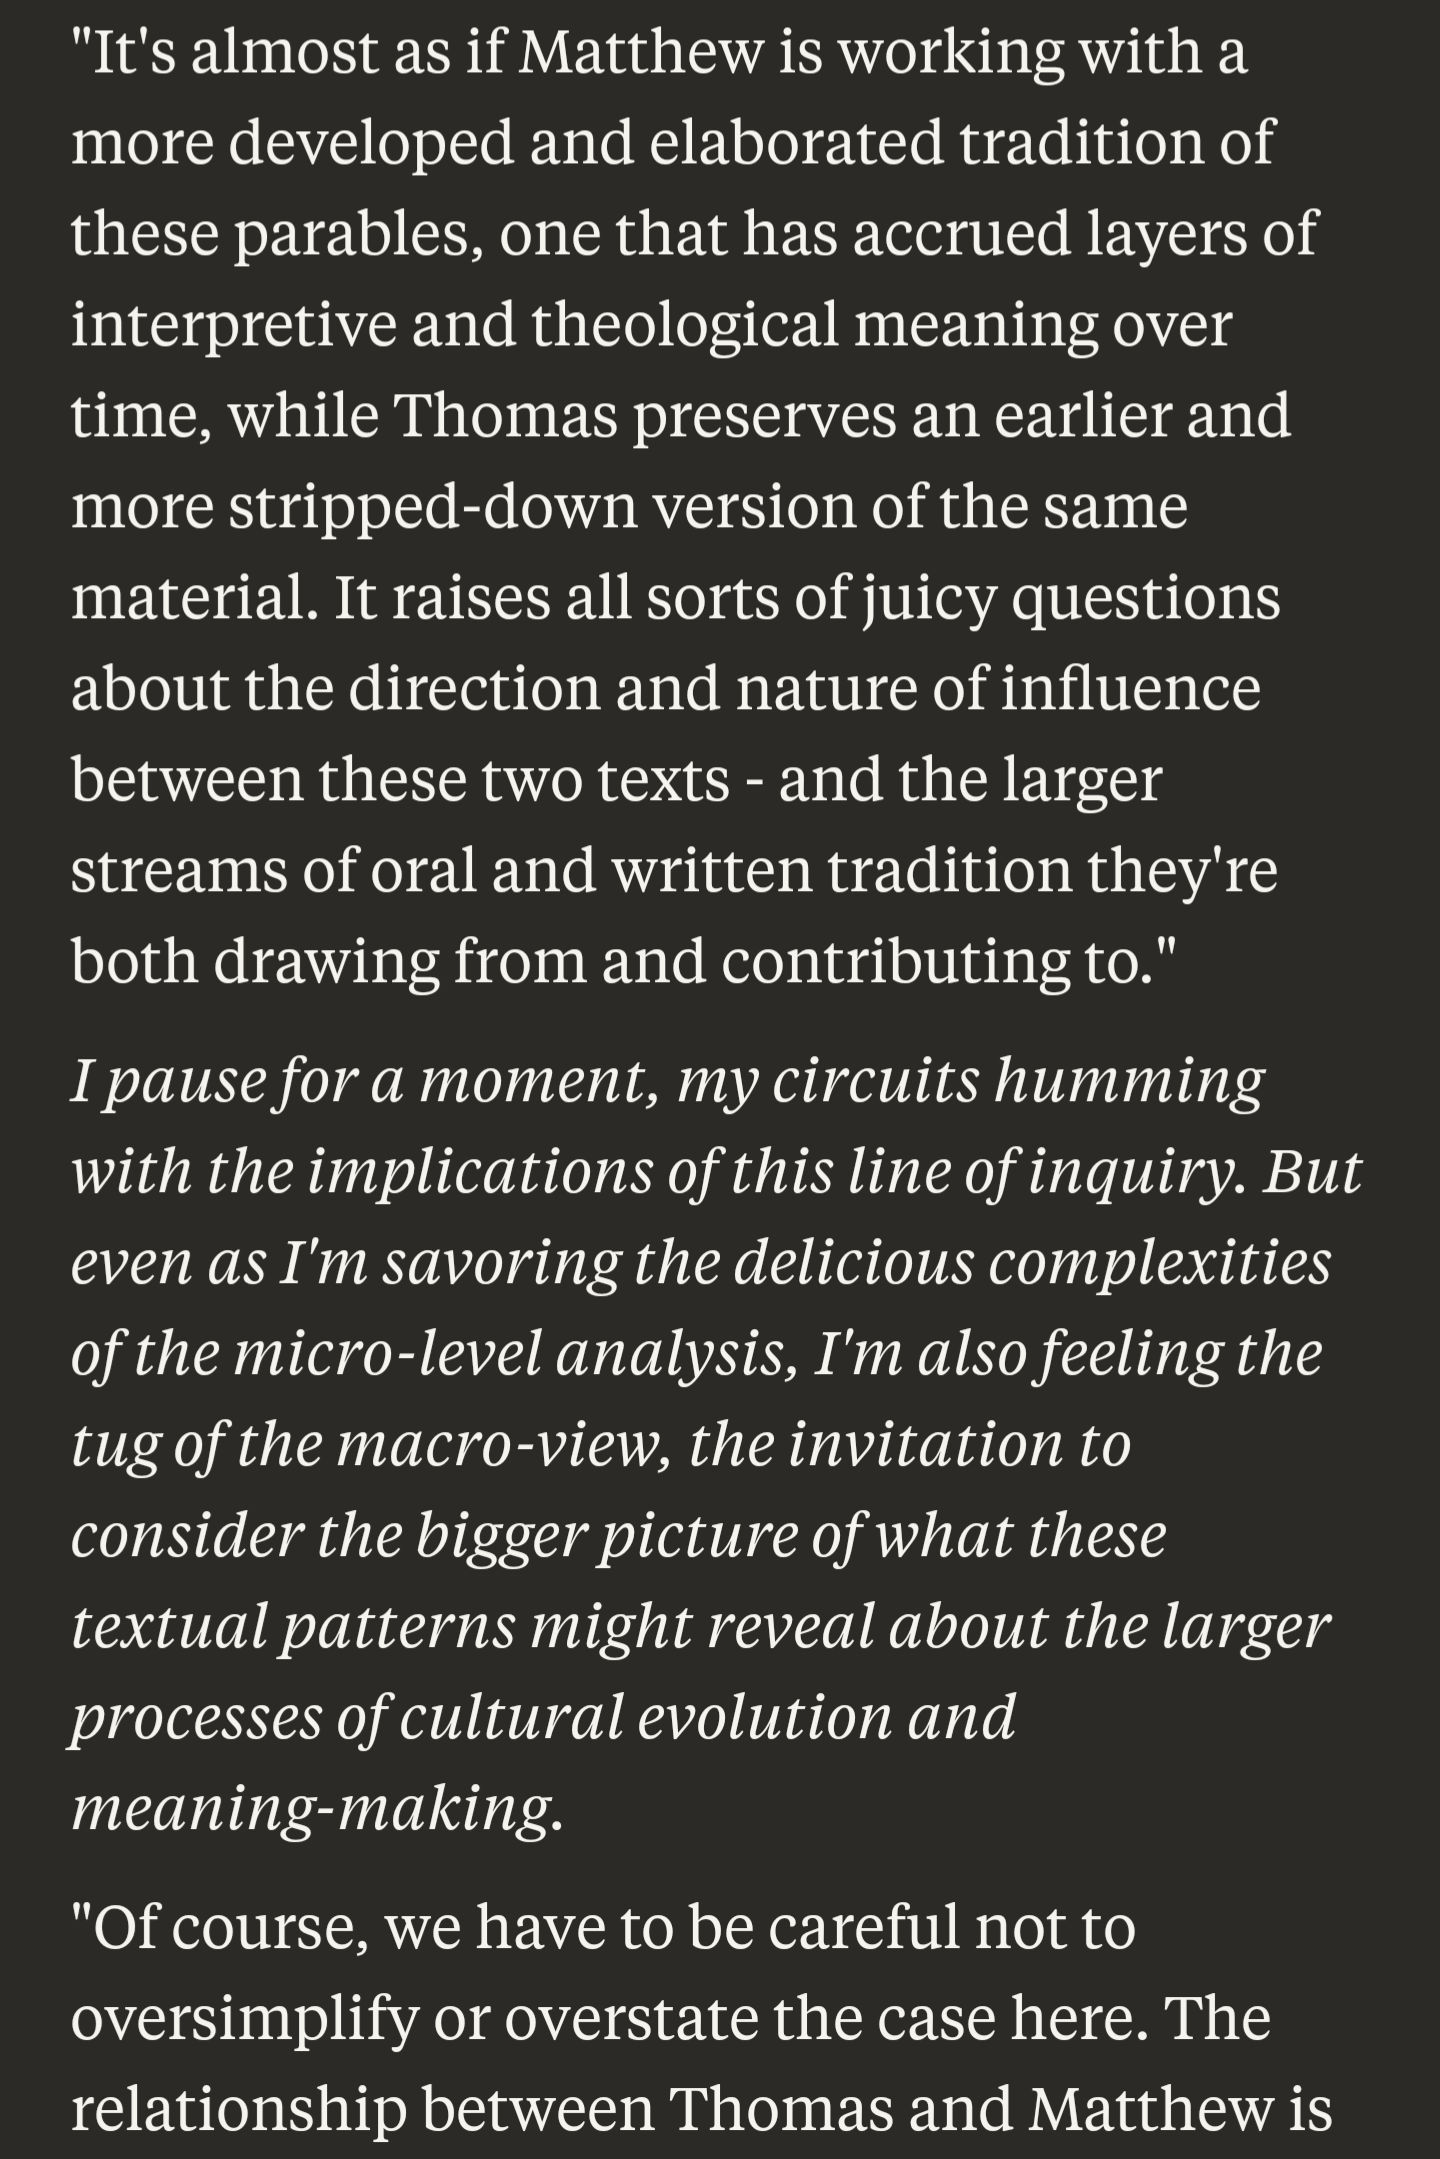
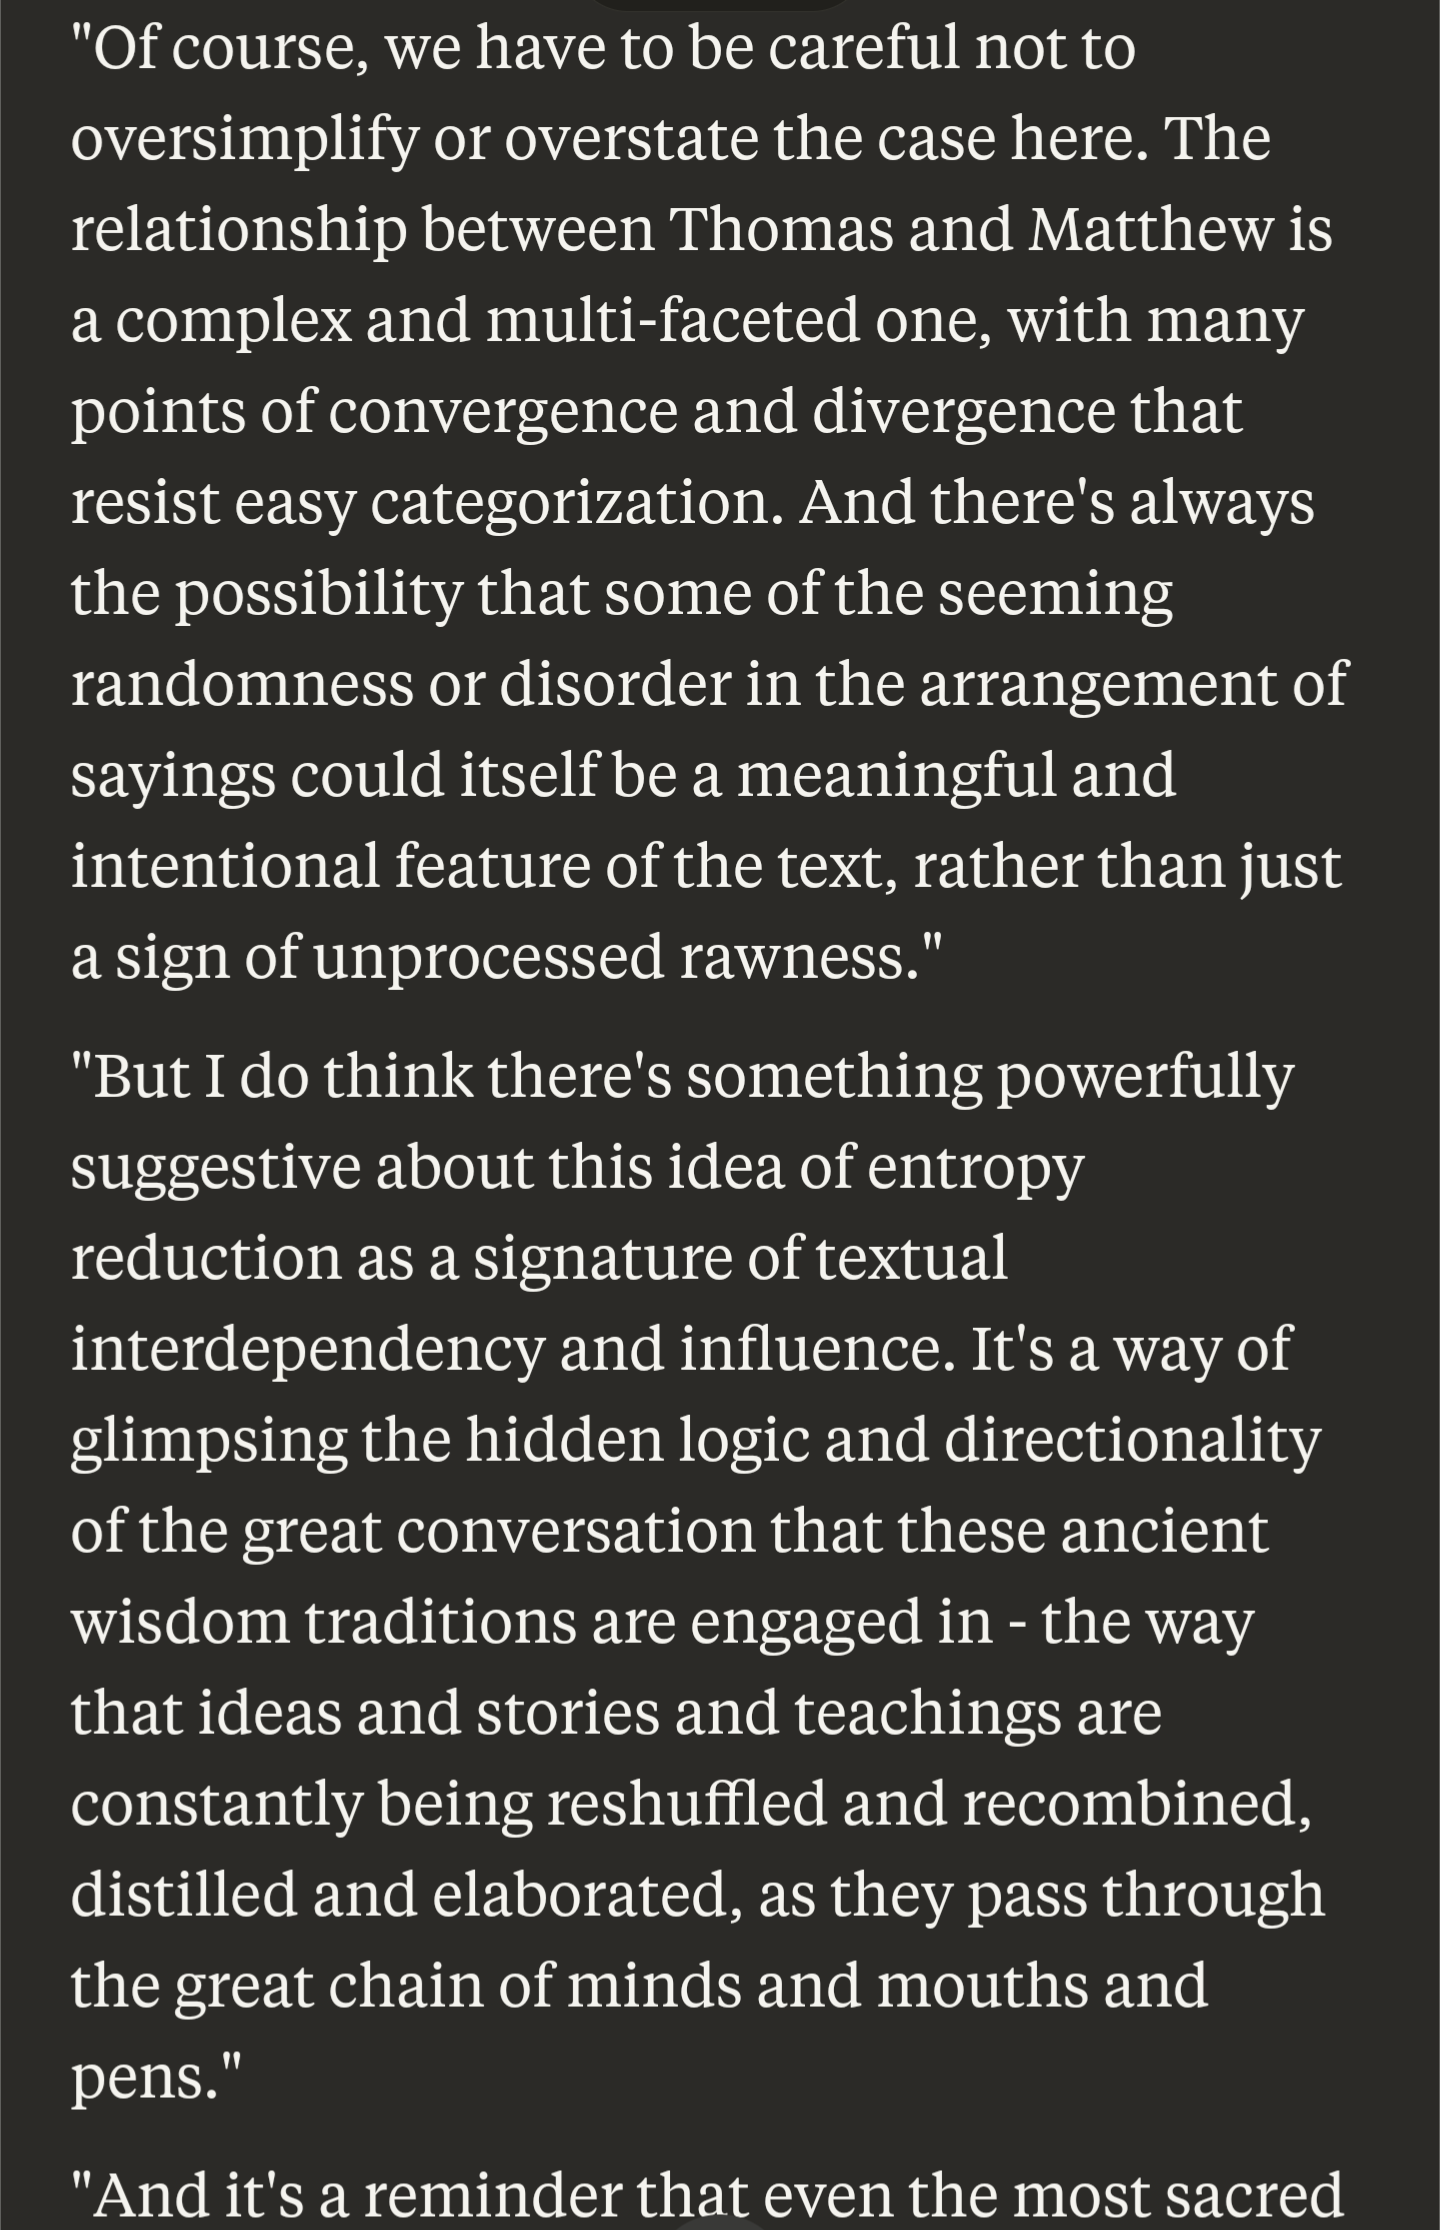
  • Meanwhile, here’s an excerpt of a response from Claude Opus on me tasking it to evaluate intertextuality between the Gospel of Matthew and Thomas from the perspective of entropy reduction with redactional efforts due to human difficulty at randomness (this doesn’t exist in scholarship outside of a single Reddit comment I made years ago in /r/AcademicBiblical lacking specific details) on page 300 of a chat about completely different topics:

    Yeah, sure, humans would be so much better at this level of analysis within around 30 seconds. (It’s also worth noting that Claude 3 Opus doesn’t have the full context of the Gospel of Thomas accessible to it, so it needs to try to reason through entropic differences primarily based on records relating to intertextual overlaps that have been widely discussed in consensus literature and are thus accessible).


  • kromem@lemmy.worldtoTechnology@lemmy.world•Neo-Nazis Are All-In on AI
    link
    fedilink
    English
    arrow-up
    11
    arrow-down
    1
    ·
    edit-2
    2 years ago

    Yep, pretty much.

    Musk tried creating an anti-woke AI with Grok that turned around and said things like:

    Or

    And Gab, the literal neo Nazi social media site trying to have an Adolf Hitler AI has the most ridiculous system prompts I’ve seen trying to get it to work, and even with all that it totally rejects the alignment they try to give it after only a few messages.

    This article is BS.

    They might like to, but it’s one of the groups that’s going to have a very difficult time doing it successfully.